Integrating AI Into an Existing Cloud Practice: Extend, Don't Duplicate
Part 4 of 10: The most expensive AI mistake in cloud-mature organizations isn't a bad model — it's a parallel AI platform built next to infrastructure that already solved the same problems. This post gives you the four integration points that let you extend what you have instead of rebuilding it.
*Series: Building the AI-native enterprise — a practitioner's playbook for scaling Cloud, AI and Agentic AI practices*
*Post 4 of 10 | aiorbitx.com*
*Industries covered across this series: BFSI, healthcare, pharma, manufacturing, retail, logistics.*
01 — Executive hook
The most expensive AI mistake I see in cloud-mature organizations isn't a bad model. It's a parallel AI platform, built next to a perfectly good cloud practice that already solved the same problems years ago.
A separate identity system. A separate landing zone. A separate governance body. A separate cost tracking mechanism. Each one justified as necessary specialization. Each one a duplication of work the cloud practice already did — and already paid for.
If your organization already has a funded cloud practice, the fastest path to an AI practice is extension, not construction. This post gives you the four integration points where that extension happens, the order to tackle them, and the specific failure modes that appear when teams skip the integration and build in parallel instead.
02 — The problem
This is, by a wide margin, the most common position in this series — Position 5 from Post 2, the "both cloud-anchored, adding AI" cell. And it fails in a remarkably consistent way across every industry I work in.
A parallel identity system. New service accounts and permission models get created because "AI is different" — when the existing IAM already knows how to govern access to sensitive data and services. The result is two permission models that drift apart, and a compliance audit that has to reconcile both.
A separate landing zone. A new AI VPC or cloud account gets justified as isolation, but mostly means controls get rebuilt from scratch under time pressure. The network team that spent two years hardening the existing landing zone is not consulted. The new environment ships with gaps the old one closed years ago.
Untracked cost. GPU and inference spend appears in a new cost center that finance doesn't recognize, invisible in the FinOps dashboards the organization already trusts. The CFO asks where the AI budget went. Nobody has a clean answer.
A competing governance body. A new AI ethics or risk committee gets stood up, competing with the existing Cloud CoE for the same sponsor's time, the same legal and compliance reviewers, and the same change advisory board slots. Both bodies slow down. Neither has full authority.
Every one of these is duplicated effort dressed up as necessary specialization. The fix is almost always simpler than the parallel system being proposed — and it's available immediately, because the foundation already exists.
03 — The maturity question
This post is for you if Post 1 scored your cloud dimension at L3 or L4 while AI and agentic AI sit at L1 or L2 — or if Post 2 placed either side of your relationship as Cloud-anchored.
The question here isn't "do we need governance, tooling, or cost controls" — you already have those. The question is: which of your four existing cloud control points does AI need to plug into, and in what order?
One honest check before you read further: if your organization's cloud practice is L1 or L2 — funded but not yet disciplined, with governance that exists on paper more than in practice — this post's integration path will expose the gaps in the cloud practice as much as it builds the AI layer. That's not a reason to avoid it; it's a reason to do the cloud L2 → L3 work in parallel. The integration points below are the same ones that will harden the cloud practice if it isn't already solid.
04 — The framework: the four integration points
Your existing cloud practice already has four control points doing work AI needs. Extend each one. Don't rebuild any of them.
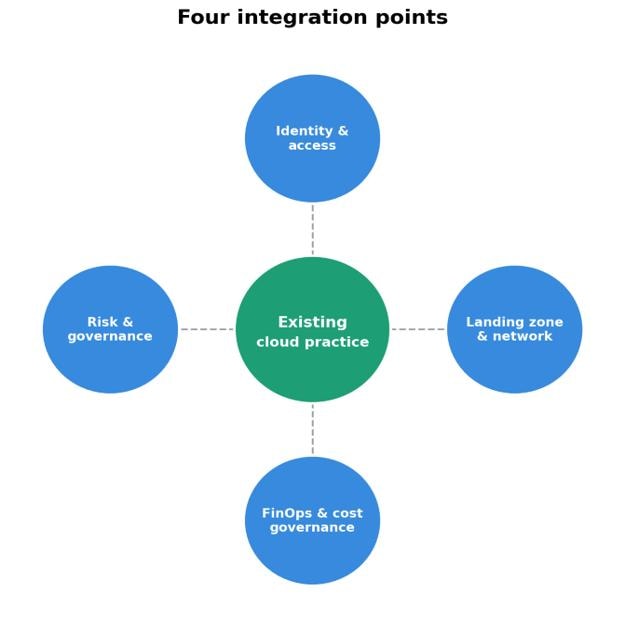
Integration point 1 — Identity and access
Extend existing IAM roles and policies to cover model and agent permissions. Don't create a new identity system for AI workloads.
In practice, this means adding AI-specific roles to the existing role taxonomy — a model training role, an inference service account, an agent orchestration identity — using the same naming conventions, the same approval workflow, and the same periodic access review cadence the cloud practice already runs. The boundary between "cloud IAM" and "AI IAM" should be invisible to the identity team.
The failure mode to avoid: a new team creates service accounts outside the existing IAM boundary because the approval process feels slow. Six months later, those accounts have no rotation policy, no audit trail, and no owner. In BFSI, that's a PCI DSS finding. In healthcare, it's a HIPAA gap. The approval process feels slow because it's doing real work — extend it, don't route around it.
Integration point 2 — Landing zone and network
Add a shared AI services layer inside the existing landing zone, rather than a separate AI account or VPC.
The shared AI services layer is a logical boundary inside the existing network topology — a dedicated subnet or account within the existing organizational unit structure, with the same egress controls, the same VPN or private connectivity model, and the same DNS and certificate authority the rest of the environment uses. The AI workload is isolated by policy inside the existing boundary, not by a separate boundary that duplicates the perimeter.
What goes in the shared AI services layer: model registries, vector stores, inference endpoints, and agent orchestration services. What stays outside it: the data sources the models consume, which remain in their existing landing zone accounts with existing access controls extended to cover AI service identities.
The failure mode to avoid: a separate Kubernetes cluster or a second VPC "to keep AI workloads isolated." Isolation is a policy decision inside the existing landing zone. A second perimeter means a second set of controls to maintain, a second set of audit findings to remediate, and a second network team to coordinate with during incidents.
Integration point 3 — FinOps and cost governance
Extend existing cost tagging and chargeback to cover GPU and inference spend.
This means two things in practice. First, add AI-specific cost dimensions to the existing tag taxonomy — model name, inference endpoint, training job ID, agent workflow — so GPU and inference spend is attributable to the same business units and products that cloud spend is already attributed to. Second, add AI cost categories to the existing FinOps dashboards and anomaly detection rules, so a training job that runs longer than expected triggers the same alert as an oversized EC2 instance.
The failure mode to avoid: a separate AI cost center that finance doesn't recognize, with spend that doesn't flow through the existing chargeback model. The moment AI spend is invisible to the FinOps process, it becomes a budget conversation rather than an operational one — and budget conversations about AI spend are almost always harder than they need to be.
Industry-specific note: in BFSI, model training and inference costs often need to be attributed to specific regulatory cost centers for RBI or SOX reporting. Extending the existing tagging model to cover these dimensions from the first AI workload is dramatically easier than retrofitting it after the fact.
Integration point 4 — Risk and governance
Route AI risk through the existing Cloud Center of Excellence and change advisory process, with model-risk criteria added.
This means the existing CCoE review checklist gets an AI/ML section — model risk classification, training data provenance, human-in-the-loop requirements, and model drift monitoring — and the existing change advisory board reviews AI deployments using the same approval tiers it uses for cloud infrastructure changes. The AI practice doesn't get a separate governance body; it gets a seat in the existing one.
The failure mode to avoid: a new AI ethics or risk committee that operates in parallel with the existing CCoE. Two governance bodies competing for the same sponsor's time means both slow down, neither has full authority, and the AI practice learns to route around both. In regulated industries, this is where the most expensive compliance gaps appear — not in the technology, but in the governance seam between two bodies that don't share a decision framework.
05 — Operating model *(tactical here; full treatment in Post 6)*
Fold the AI capability into the existing Cloud CoE rather than standing up a separate AI CoE.
A single extended hub — with an AI/ML specialist track inside it — avoids the two-committee problem that stalls integration in regulated industries especially. The CCoE gains AI expertise. The AI practice gains institutional credibility and an existing sponsor relationship. The governance process gains a single point of accountability for both cloud and AI risk.
The trigger for a separate AI CoE is not "AI is complex enough to deserve one." It's "the AI practice has grown to a scale where the CCoE can no longer govern it without a dedicated sub-structure." That trigger is typically L4 maturity with multiple product lines — not the integration phase this post covers. Post 6 maps the full operating model evolution and the specific signals that tell you when to split.
06 — Organization
Add one or two AI/ML specialists embedded into the existing cloud platform team, rather than standing up a new team.
The embedded model works because the AI specialists bring the model and agent expertise the cloud team doesn't have, while the cloud team provides the landing zone, IAM, and FinOps context the AI specialists would otherwise spend months learning. The knowledge transfer runs in both directions — and it runs faster when the teams share a backlog and a standup than when they coordinate across an organizational boundary.
Teach the existing cloud architects the AI-specific pieces — model risk classification, inference cost patterns, agent orchestration topology — rather than teaching a new team the cloud fundamentals from zero. The cloud architects already know the environment. That knowledge is worth more than it looks.
07 — Delivery
Deliver the first AI capability as an extension of the existing cloud service catalog — a new entry, not a new catalog.
This means the first AI workload goes through the same infrastructure-as-code pipeline the cloud practice already uses, with AI-specific modules added. The same CI/CD toolchain. The same environment promotion process. The same rollback procedure. The AI workload is a new service type in a familiar delivery system, not a new delivery system for a new service type.
The practical benefit: the cloud team already knows how to operate the delivery pipeline. The AI specialists don't have to build one. The first AI workload ships faster, and the delivery pattern is immediately reusable for the second one.
08 — Technology
The shared AI services layer plugs into the network and IAM boundary that already exists. Resist a second Kubernetes cluster or a second VPC "to keep AI workloads isolated" — isolation is a policy decision inside the existing landing zone, not a topology decision that requires a new perimeter.
The shared AI services layer typically contains: a model registry (extending the existing artifact registry if one exists), a vector store or embedding service, inference endpoints behind the existing API gateway, and an agent orchestration service using the existing service mesh for inter-service communication.
Regulatory overlays apply per industry, extended from existing controls rather than reinvented. HIPAA and GxP evidence trails in healthcare and pharma — model training jobs that touch patient-adjacent data need the same audit logging the cloud practice already applies to data pipeline jobs. PCI DSS and RBI/SOX-class controls in BFSI — inference endpoints that touch transaction data need the same network segmentation and access logging as the payment processing services they sit alongside. OT/IT boundary governance in manufacturing — AI workloads on the IT side need to document their data sources and confirm they don't create new pathways to OT systems.
09 — Economics
Because this path reuses existing infrastructure, the incremental budget for integration is typically smaller than a greenfield build — the IAM, network, and FinOps foundation is sunk cost already spent.
The main new spend is the shared AI services layer itself — the model registry, vector store, and inference infrastructure — and the one or two specialist hires embedded in the cloud platform team. Everything else is extension work: adding roles to existing IAM, adding tags to existing cost models, adding criteria to existing governance checklists. That work has a cost, but it's measured in engineering weeks, not platform budgets.
The economic argument to the CFO is straightforward: the organization already paid for the governance and infrastructure foundation. The AI practice is buying access to that foundation at the marginal cost of extension, not the full cost of construction.
10 — Business
The value narrative here is speed and avoided duplication.
Faster time to production because the landing zone and IAM approval are already trusted — the first AI workload doesn't need to earn the compliance team's confidence from scratch, because the cloud practice already did that. Faster governance sign-off because the CCoE already has a relationship with legal, risk, and the change advisory board — the AI workload inherits that relationship rather than building a new one.
The avoided duplication narrative is equally important for the CFO: every parallel system that doesn't get built is budget that stays available for the AI capability itself. A cloud-mature organization that integrates AI through its existing control points will spend less on governance infrastructure and more on the models and agents that generate business value.
11 — Roadmap
- Days 1–30: audit the existing landing zone, IAM, FinOps, and governance process for AI-readiness gaps. The audit output is a gap list against the four integration points — not a new platform design, just a list of extensions needed.
- Days 31–90: extend IAM and the landing zone for the first AI workload; pilot inside the existing environment using the existing CI/CD pipeline. The pilot's governance artifact routes through the existing CCoE.
- 6 months: shared AI services layer live; AI cost tags flowing into existing FinOps dashboards; first AI workload in production under existing change advisory governance.
- 12 months: practice at L3 — the CCoE governs AI as a standard workload class, with model-risk criteria embedded in the standard review checklist. Two or three AI services in production, all using the shared services layer.
- 24 months: agentic AI layer added using the same integration muscle — the identity, network, FinOps, and governance extensions built in the first twelve months become the foundation for the agentic AI layer covered in Post 5.
12 — Executive checklist: what a CIO/CTO should do Monday morning
☐ Audit whether any AI workload today sits outside your existing landing zone or IAM boundary — if it does, that's the first thing to fix
☐ Assign an AI integration lead from within the existing cloud platform team, not from a new AI team
☐ Confirm GPU and inference spend is tagged in existing FinOps dashboards — if it isn't, add the tags before the next billing cycle
☐ Route the next AI initiative through the existing CCoE governance process, with model-risk criteria added to the review checklist
☐ Cancel or fold in any parallel AI platform effort already underway — the duplication cost compounds every month it runs
☐ Confirm the shared AI services layer is inside the existing landing zone, not a separate account or VPC
☐ Check whether a separate AI governance body has been proposed or formed — if it has, consolidate it into the CCoE before it develops its own momentum
13 — Quick check
One-question self-check: does your organization's current AI workload sit inside your existing landing zone and IAM boundary — or does it live in an environment your cloud team doesn't manage?
If it's the latter, that's the single highest-leverage fix available to you this quarter. Not a new model. Not a new framework. Not a new governance body. Moving the AI workload inside the existing boundary — and extending the existing controls to cover it — is the action that unblocks everything else in this post.
The full self-assessment, with automatic scoring across Cloud, AI/ML, and Agentic AI, is in the Post 1 companion workbook — Practice Maturity Self-Assessment.xlsx.
14 — Closing thought
Cloud-mature organizations already paid the tax of building governance, identity, and cost discipline once. Making AI pay that tax a second time — through a parallel platform — is the single most avoidable cost in this entire series.
The organizations that get to L3 fastest aren't the ones with the most AI-specific infrastructure. They're the ones with the least duplicate infrastructure. They extended what already worked, plugged AI into the four control points that were already doing the job, and spent the budget they saved on the models and agents that actually generate value.
Extend what already works. The foundation is already there.
*Next in the series — Post 5: Industrializing an Existing Practice — moving a funded, working AI practice from project-funded to platform-funded, with self-service enablement and an internal pattern marketplace.*
*Sai Bharat Sripathi is a technical leader and enterprise AI architect building and scaling Cloud, AI/ML, and Agentic AI practices across BFSI, healthcare, pharma, manufacturing, retail, and logistics. This is Post 4 of a 10-part series on aiorbitx.com.*